Webtoon Text Detection (YOLO26n)
YOLO26n detector that finds speech bubbles, narration and sound effects in webtoon pages so they can be erased before the art is reused for video. Grew the labels from 73 to 2,500 cuts across 36 works with a loop where people fix the model's drafts, and scored each version on works it had never seen: mAP50-95 rose from 0.616 to 0.844.
Why I built it
To reuse webtoon pages as source material for video generation, the speech bubbles, narration and sound effects have to be found and erased first. Art styles and bubble shapes differ from work to work, so a model trained on one work drops sharply on another. I built a detector that finds each text region as its own box.
Labeling: a loop where people fix the model’s drafts
- I dropped LLM auto-labeling. I first tried auto-labeling with Claude Haiku, but each agent judged differently and guessed coordinates by eye, so the boxes were off.
- I built my own review tool. Speech bubbles only need simple boxes, so full labeling tools felt like too much. I made an HTML review screen with shortcuts for the actions I used most.
- The model’s drafts grew the labels. I labeled a few by hand, trained, then fixed the model’s draft boxes to label more, and repeated. Approved cuts grew from 73 to 2,500 across 36 works, and labeling felt about 25% faster than drawing from scratch (a felt estimate, not a measurement).
- Cuts avoid the text. Slicing long vertical pages every 1,280px cut 23% of boxes at the seams. Slicing on rows where the model found no text brought that down to 11.5%.
Evaluation: scored on works it has never seen
Scores on later pages of the same work were too generous. A model trained on one work scored 0.85 mAP50-95 on that work’s validation set but fell to the 0.6 range on other works. So I re-scored every version on 34 works that were never used for training, and adding training works raised the score from 0.616 to 0.844. Adding more works helped more than adding more cuts from the same work.
I started with the smallest model, YOLO26n, and plan to scale up only when more data stops helping. Training ran on a local GPU (RTX 5090) at 1,280px input.
Limits and next step
- It misses shouting and burst bubbles most often, and when it catches them it can drop the spikes and tails.
- The latest model (text-v5) trained on those 34 works, so measuring unseen-work performance again needs new works.
- Next is a mask that erases the exact bubble shape instead of a box.
Demo: Korean, American and Japanese webtoons
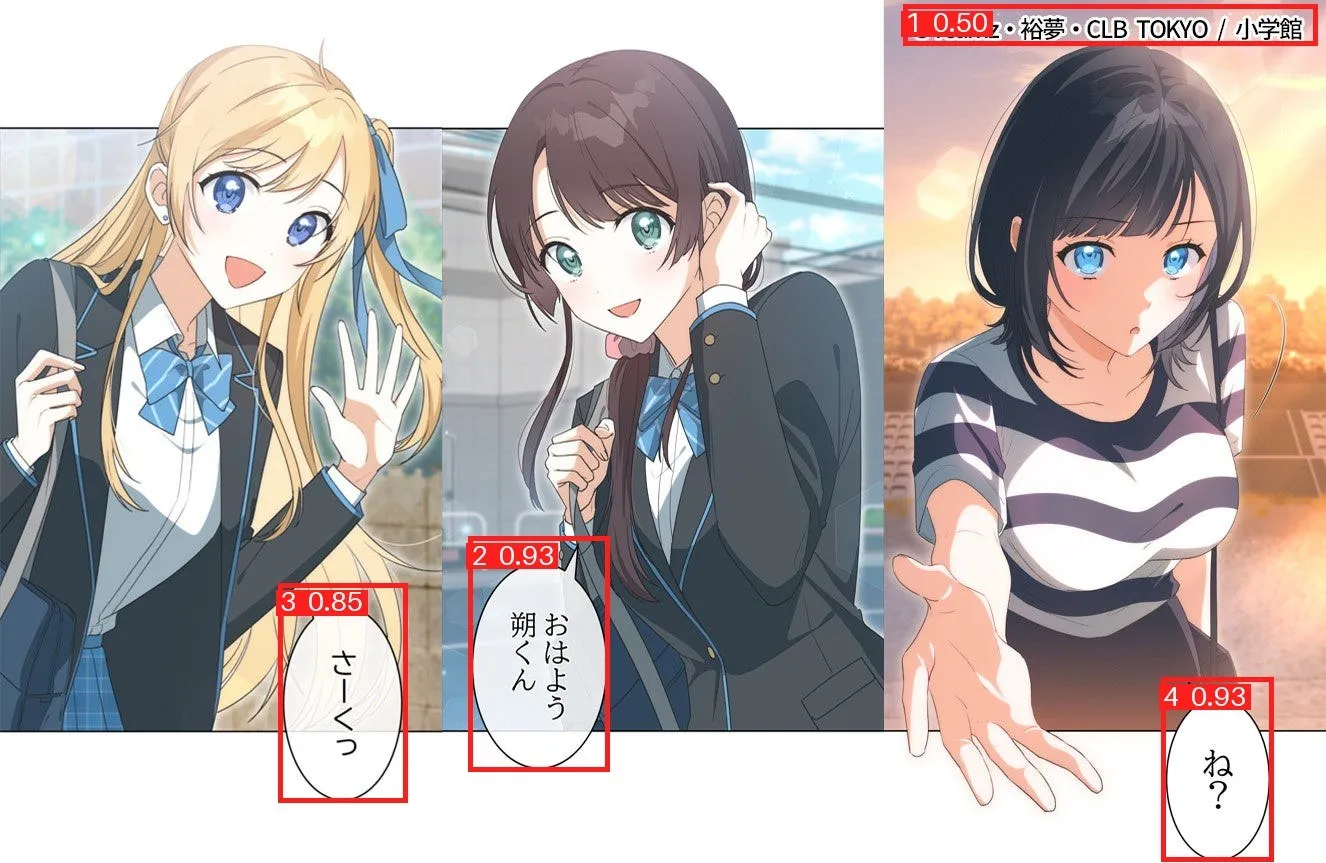
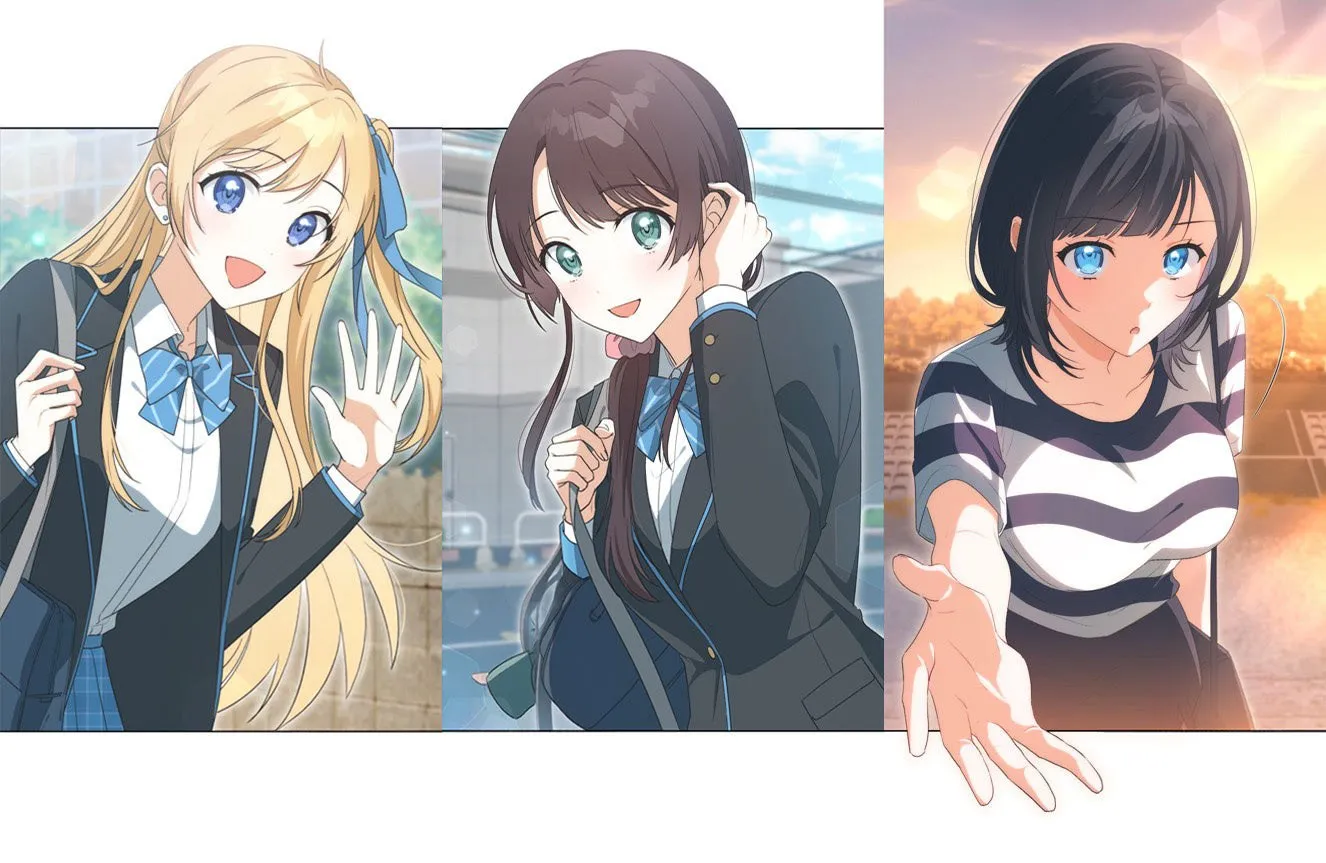
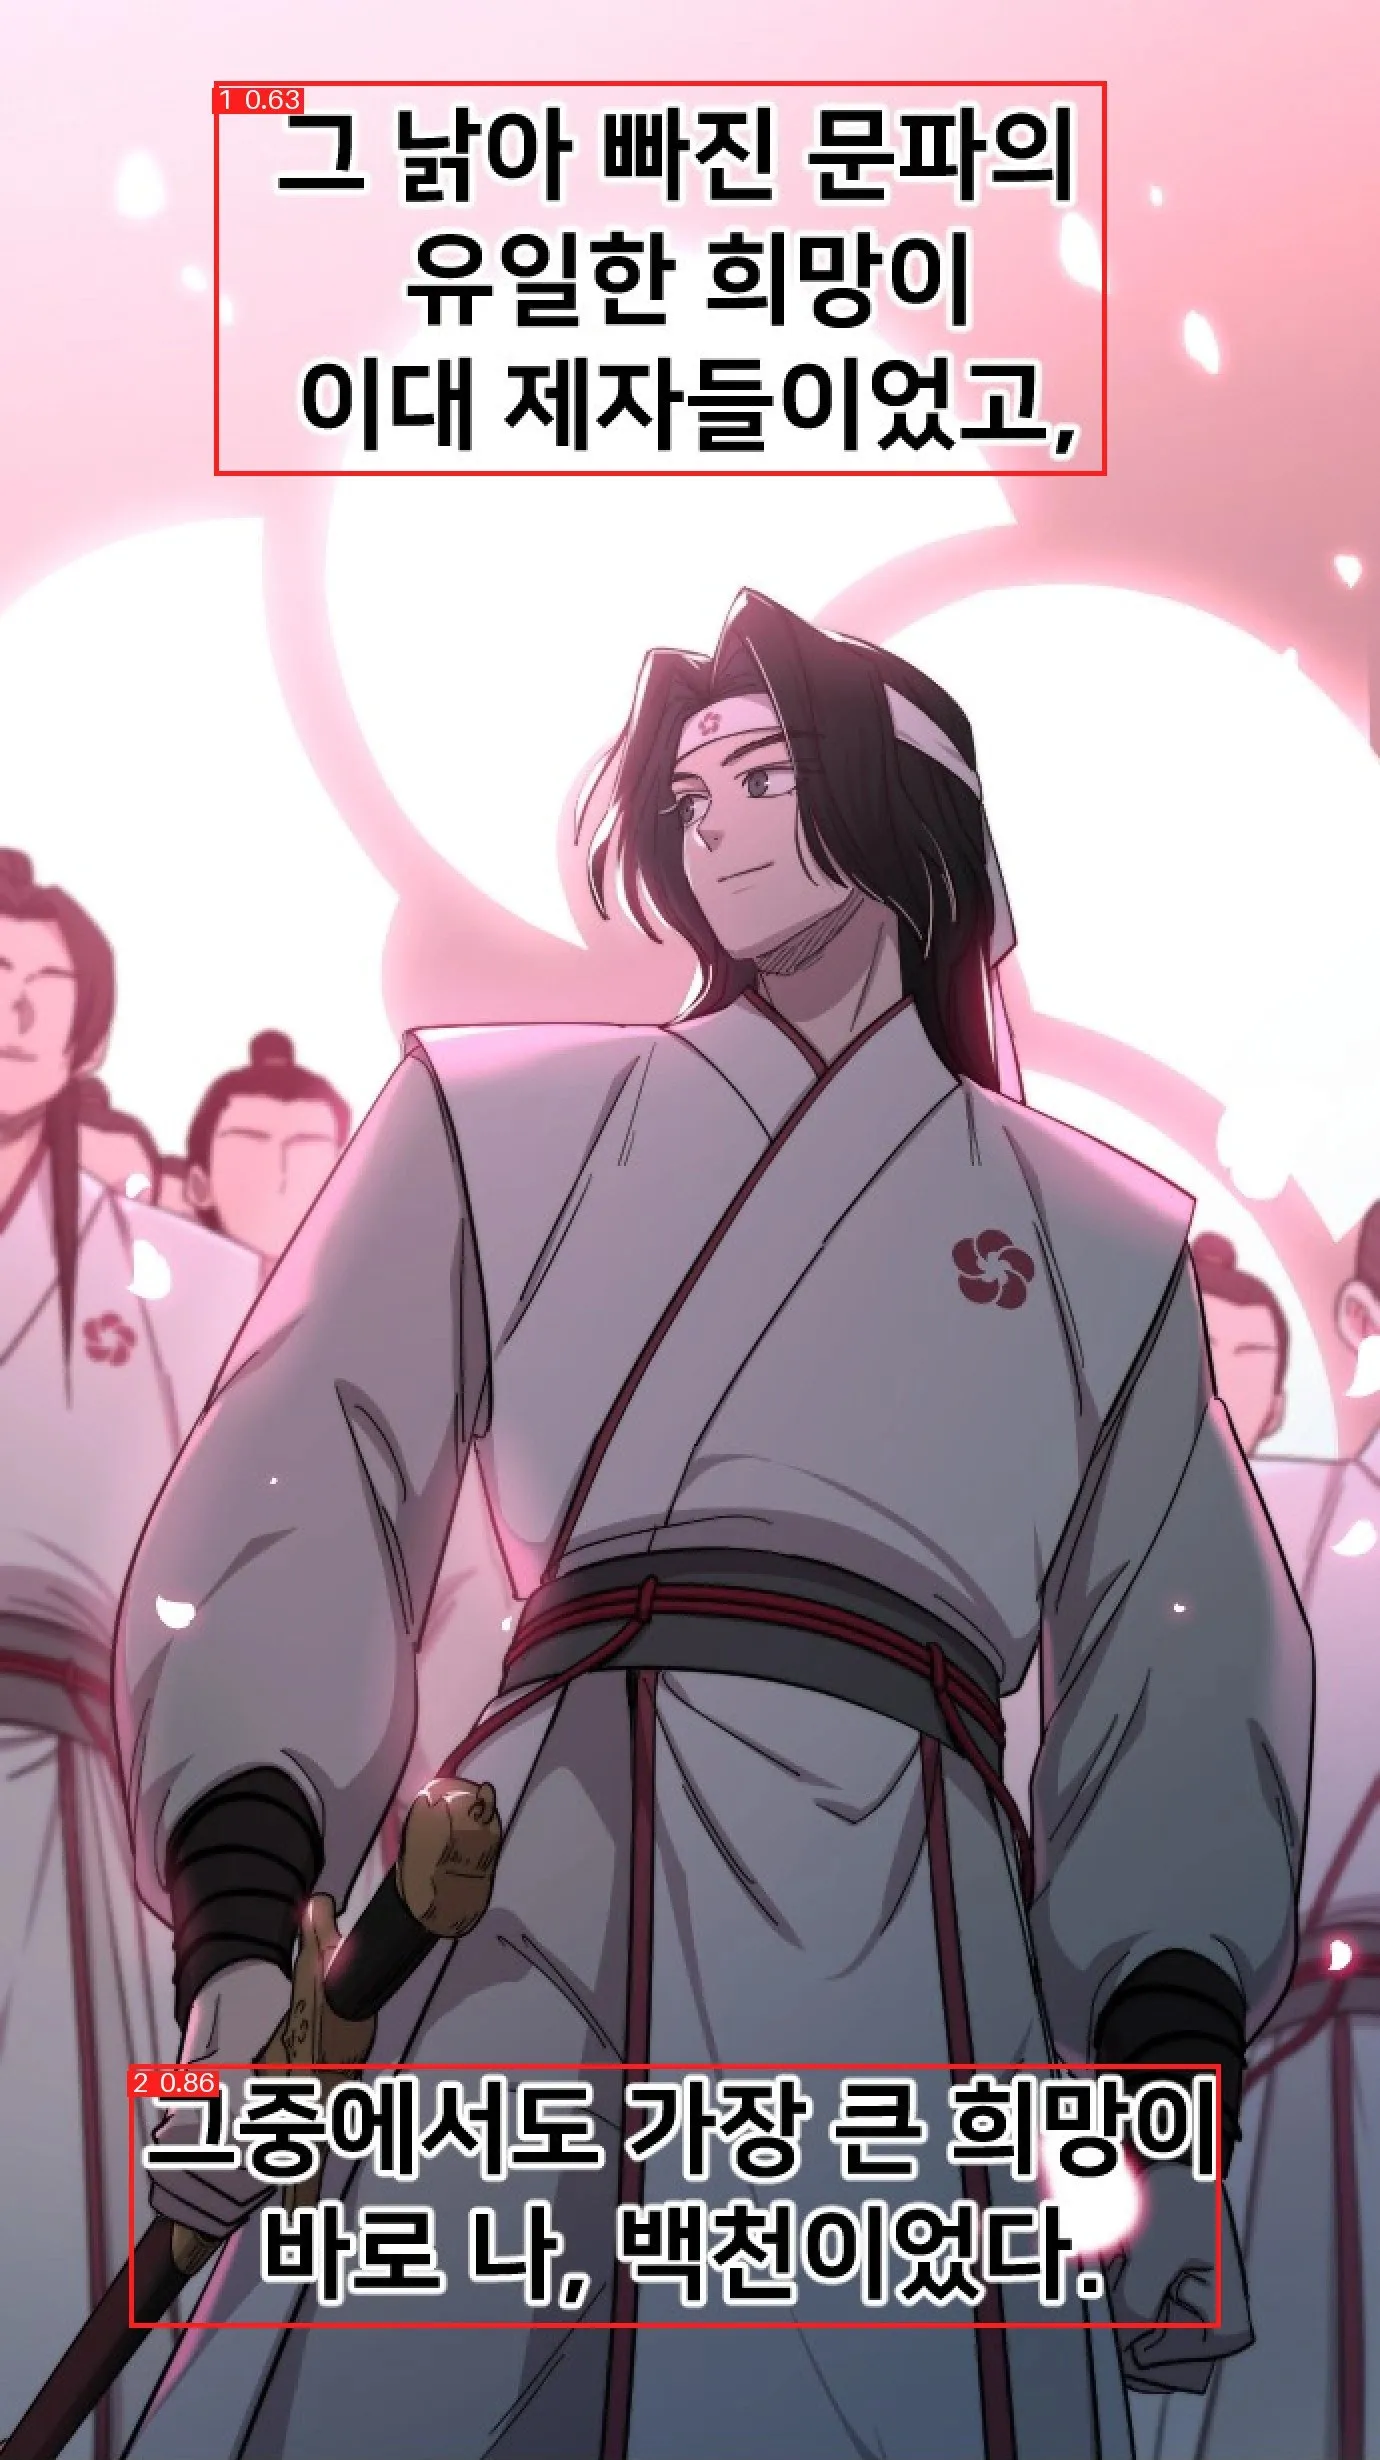
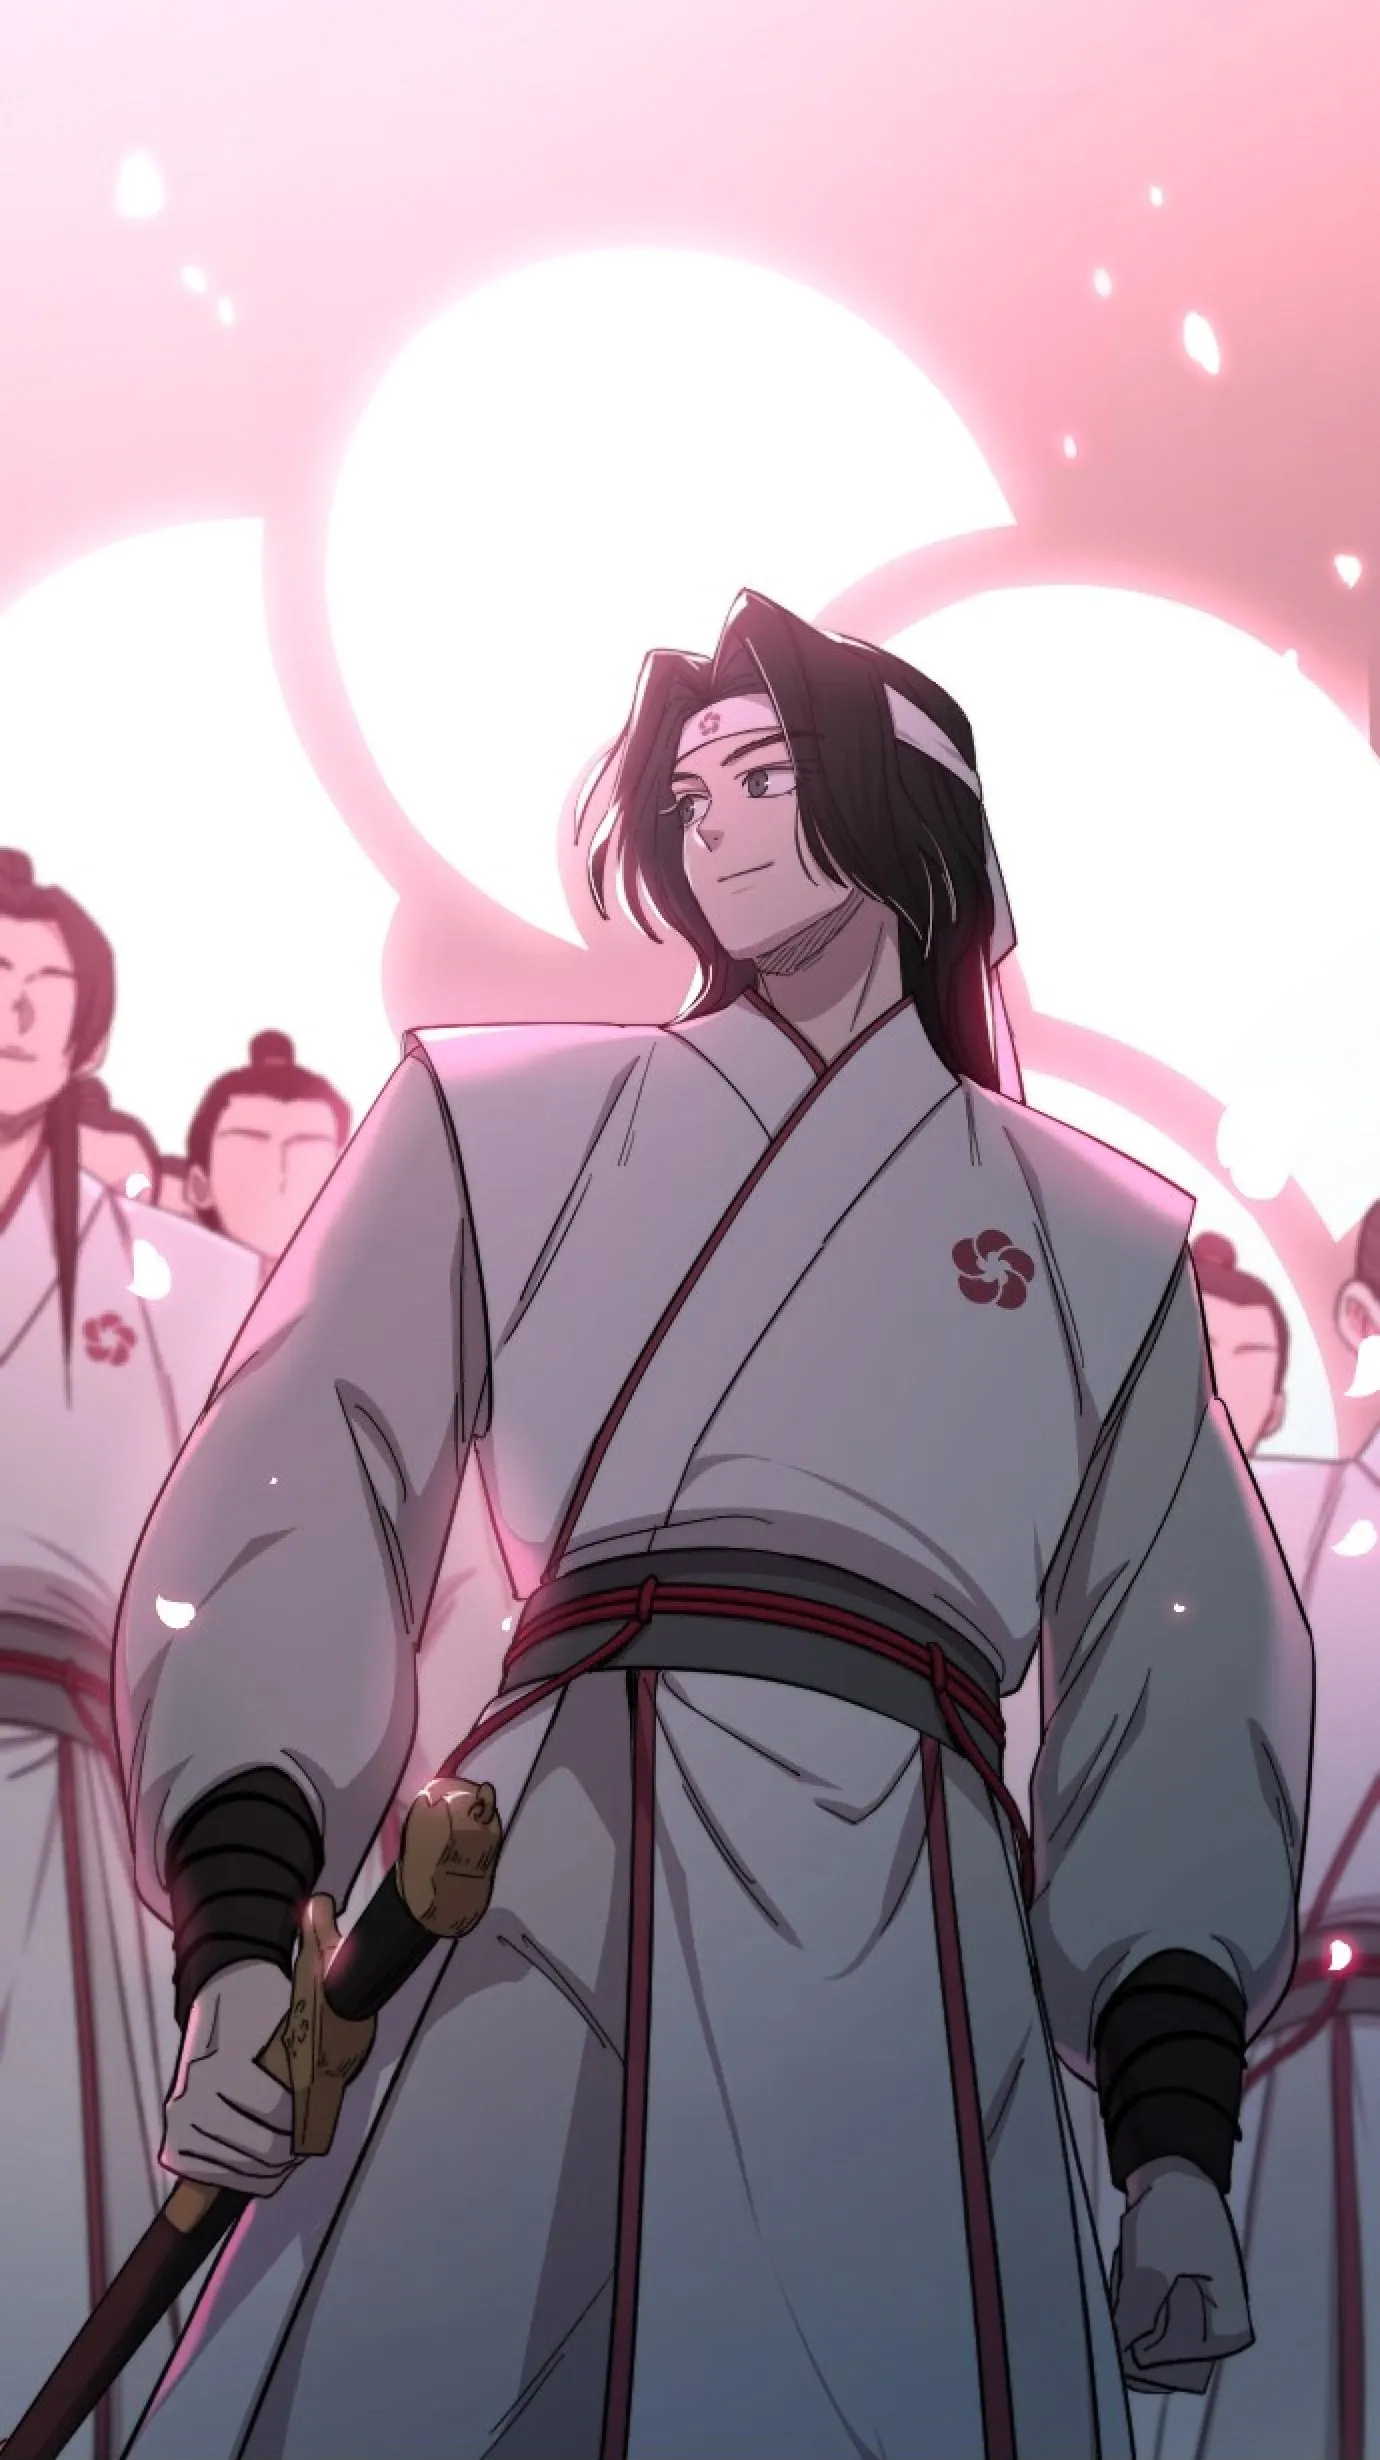
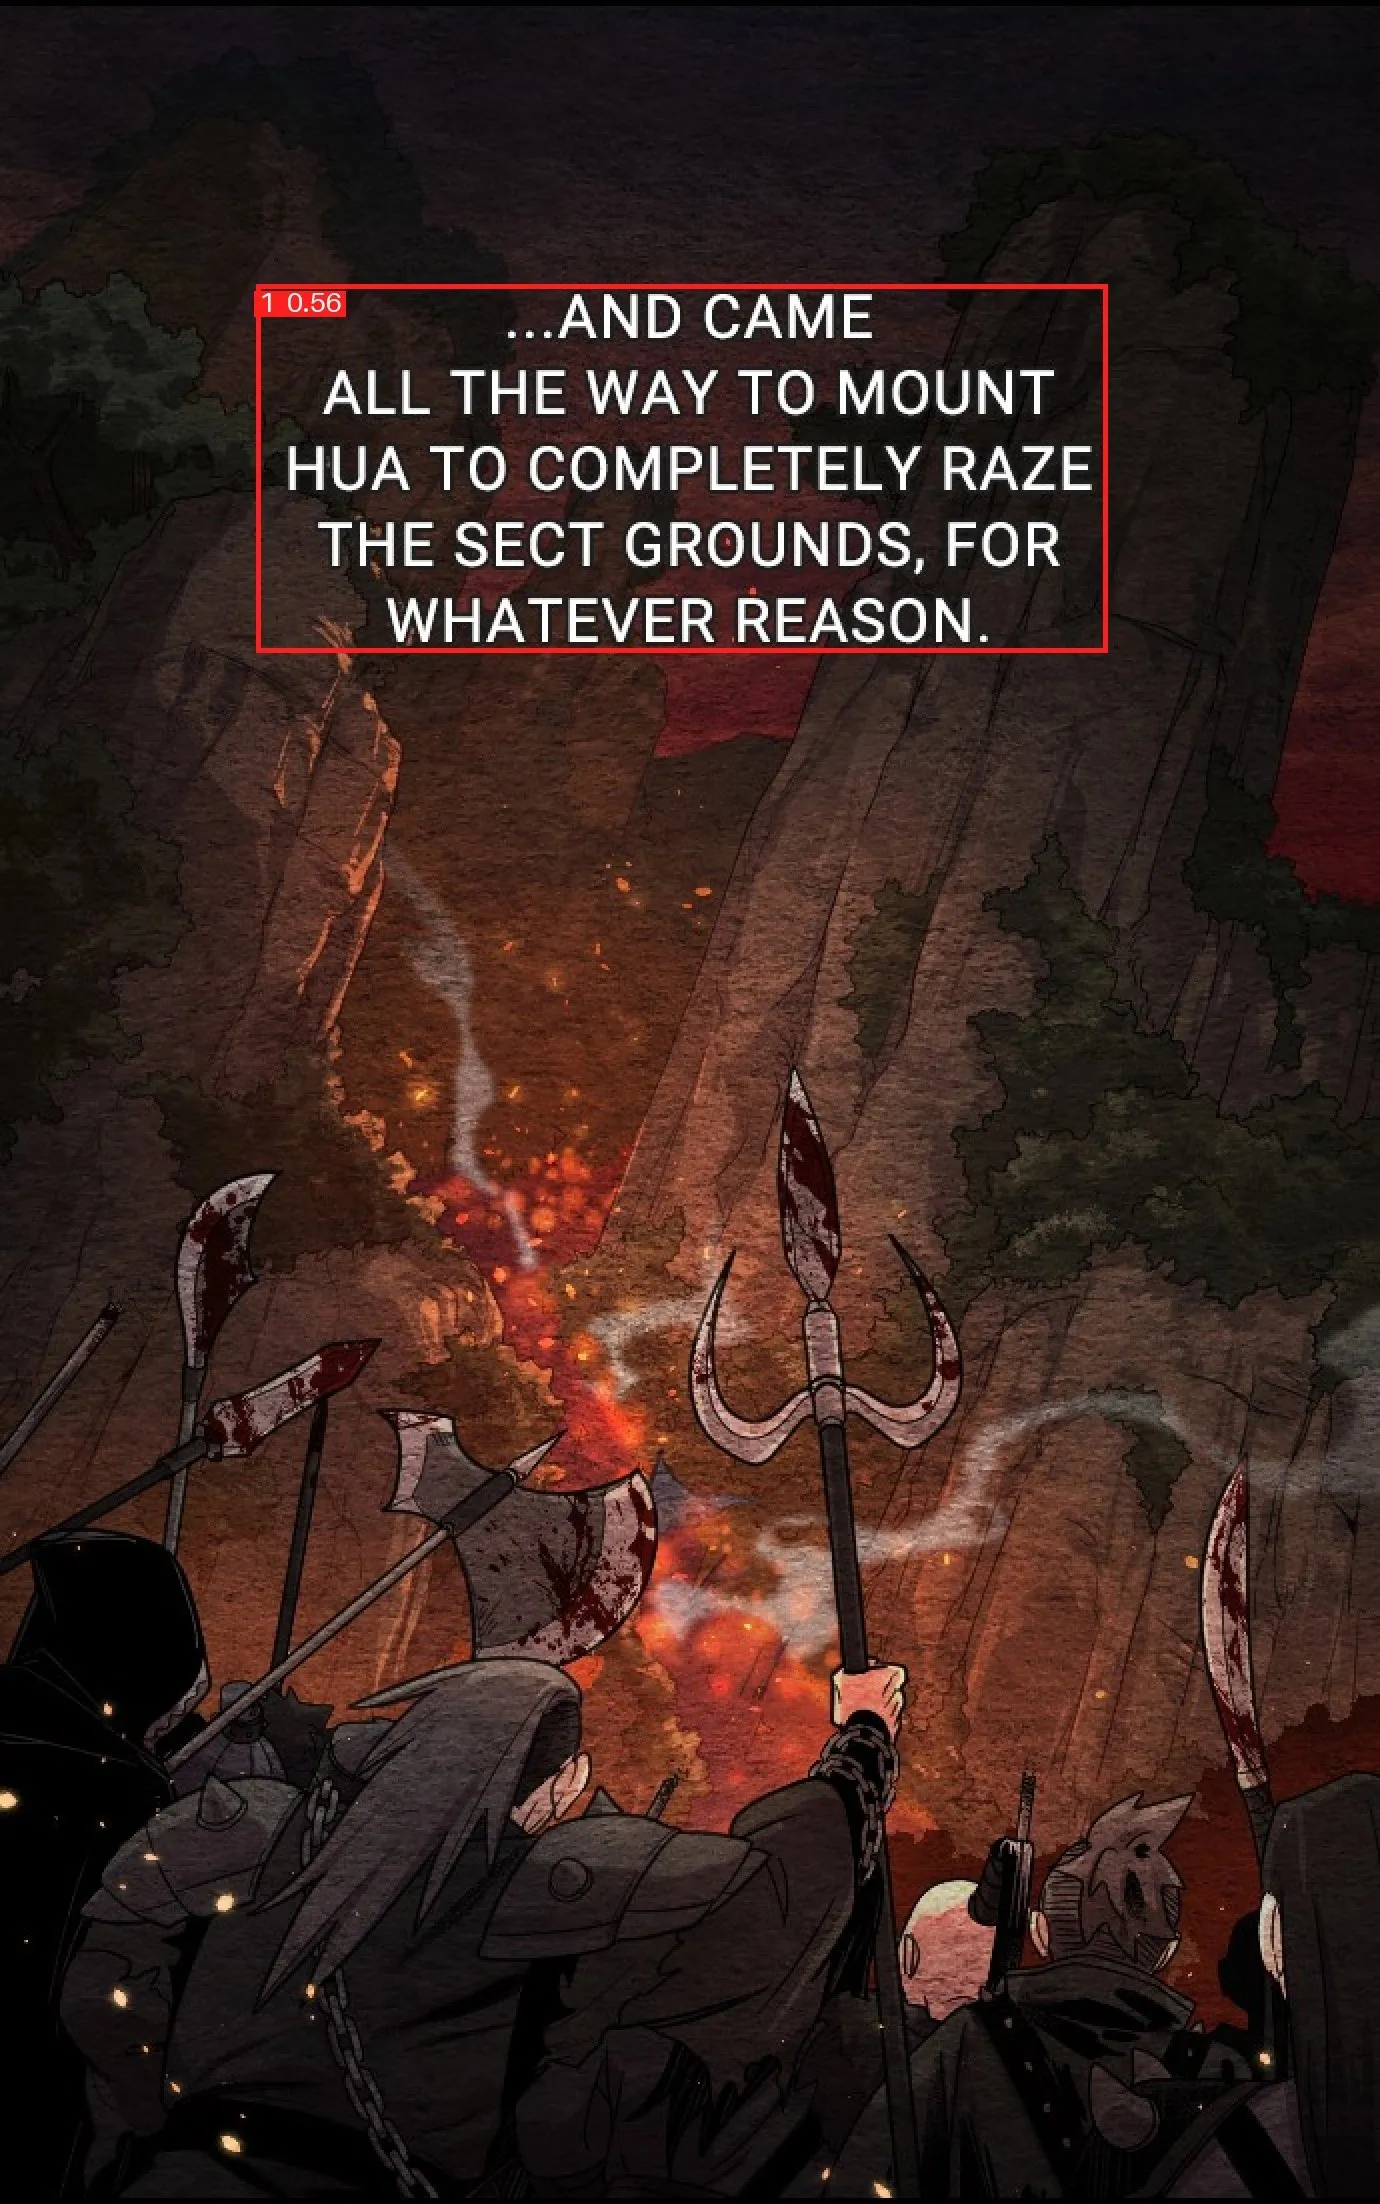
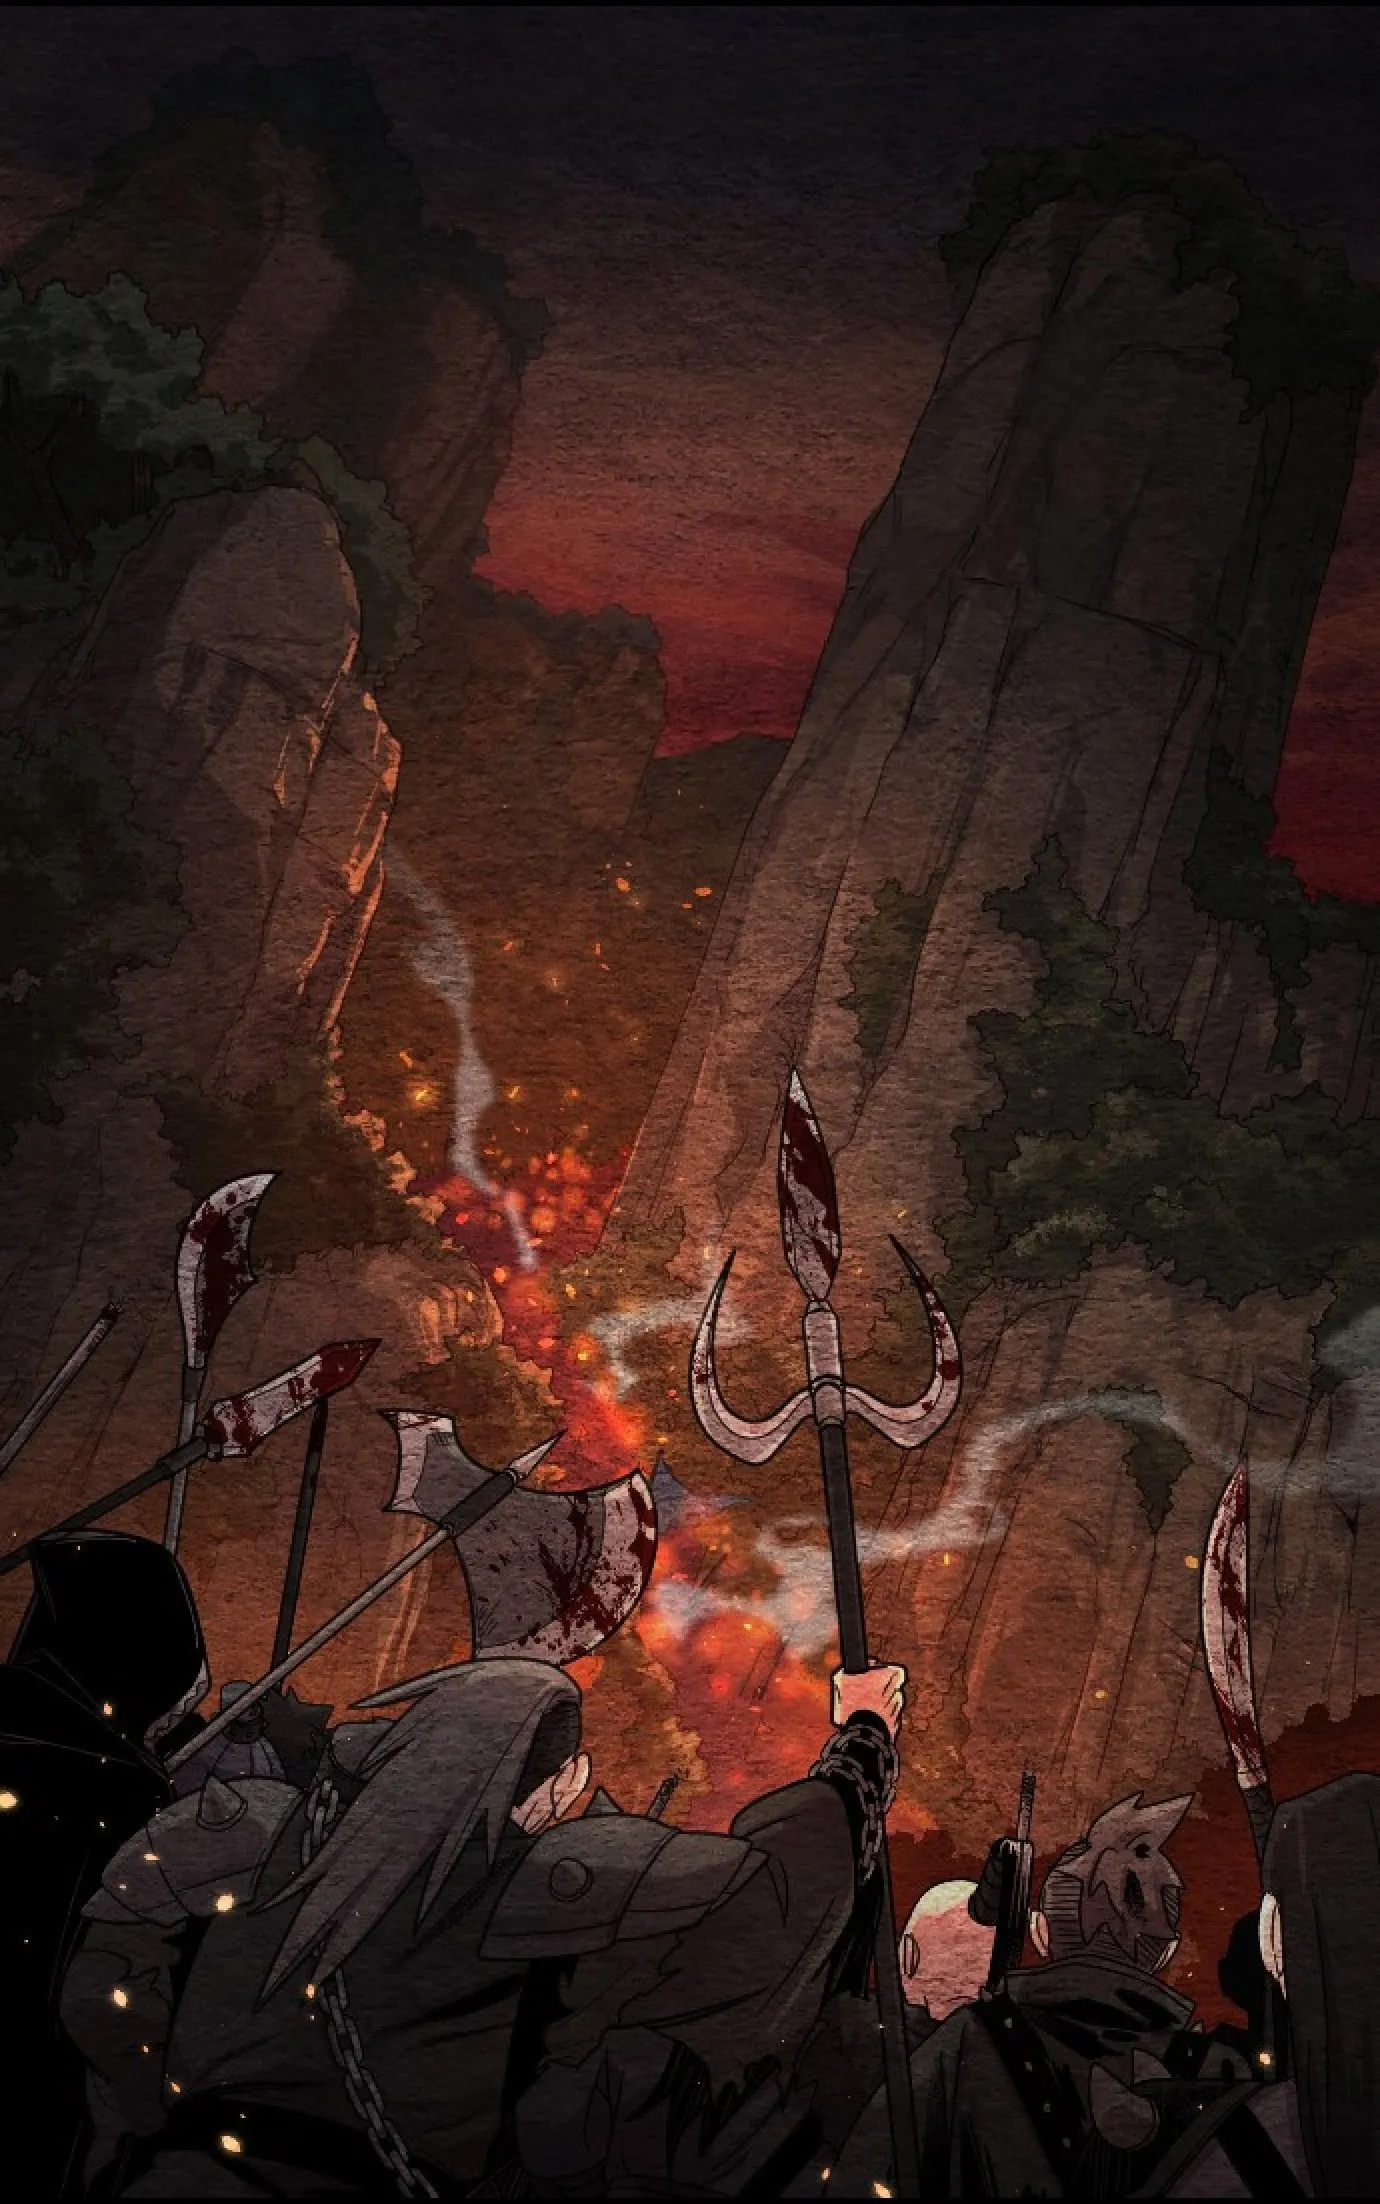
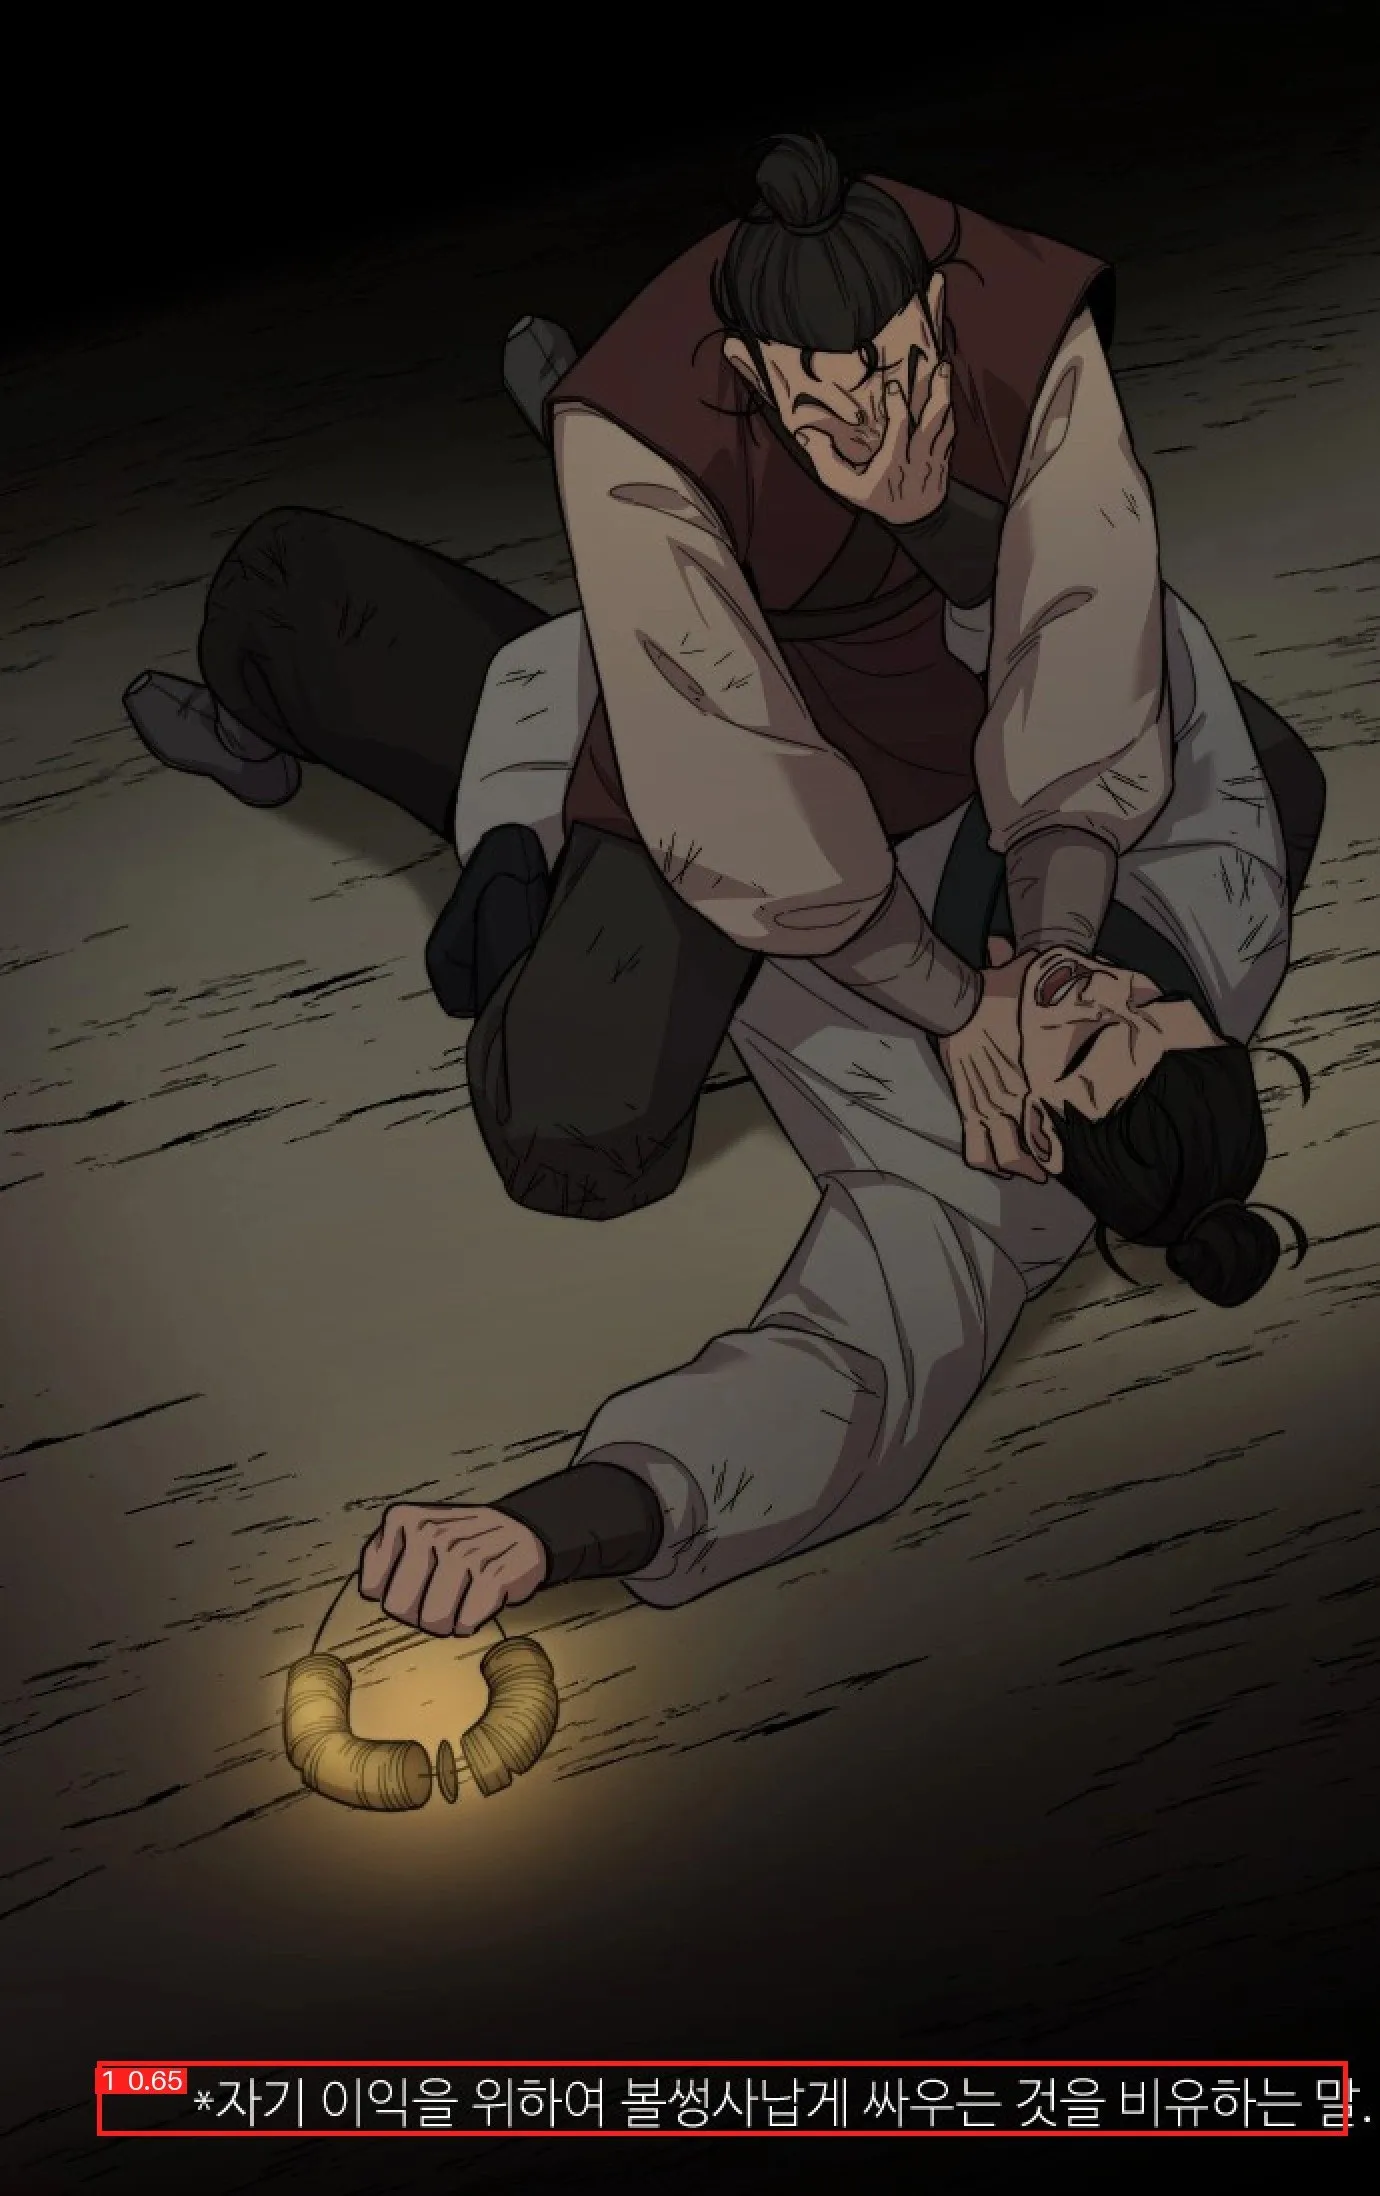
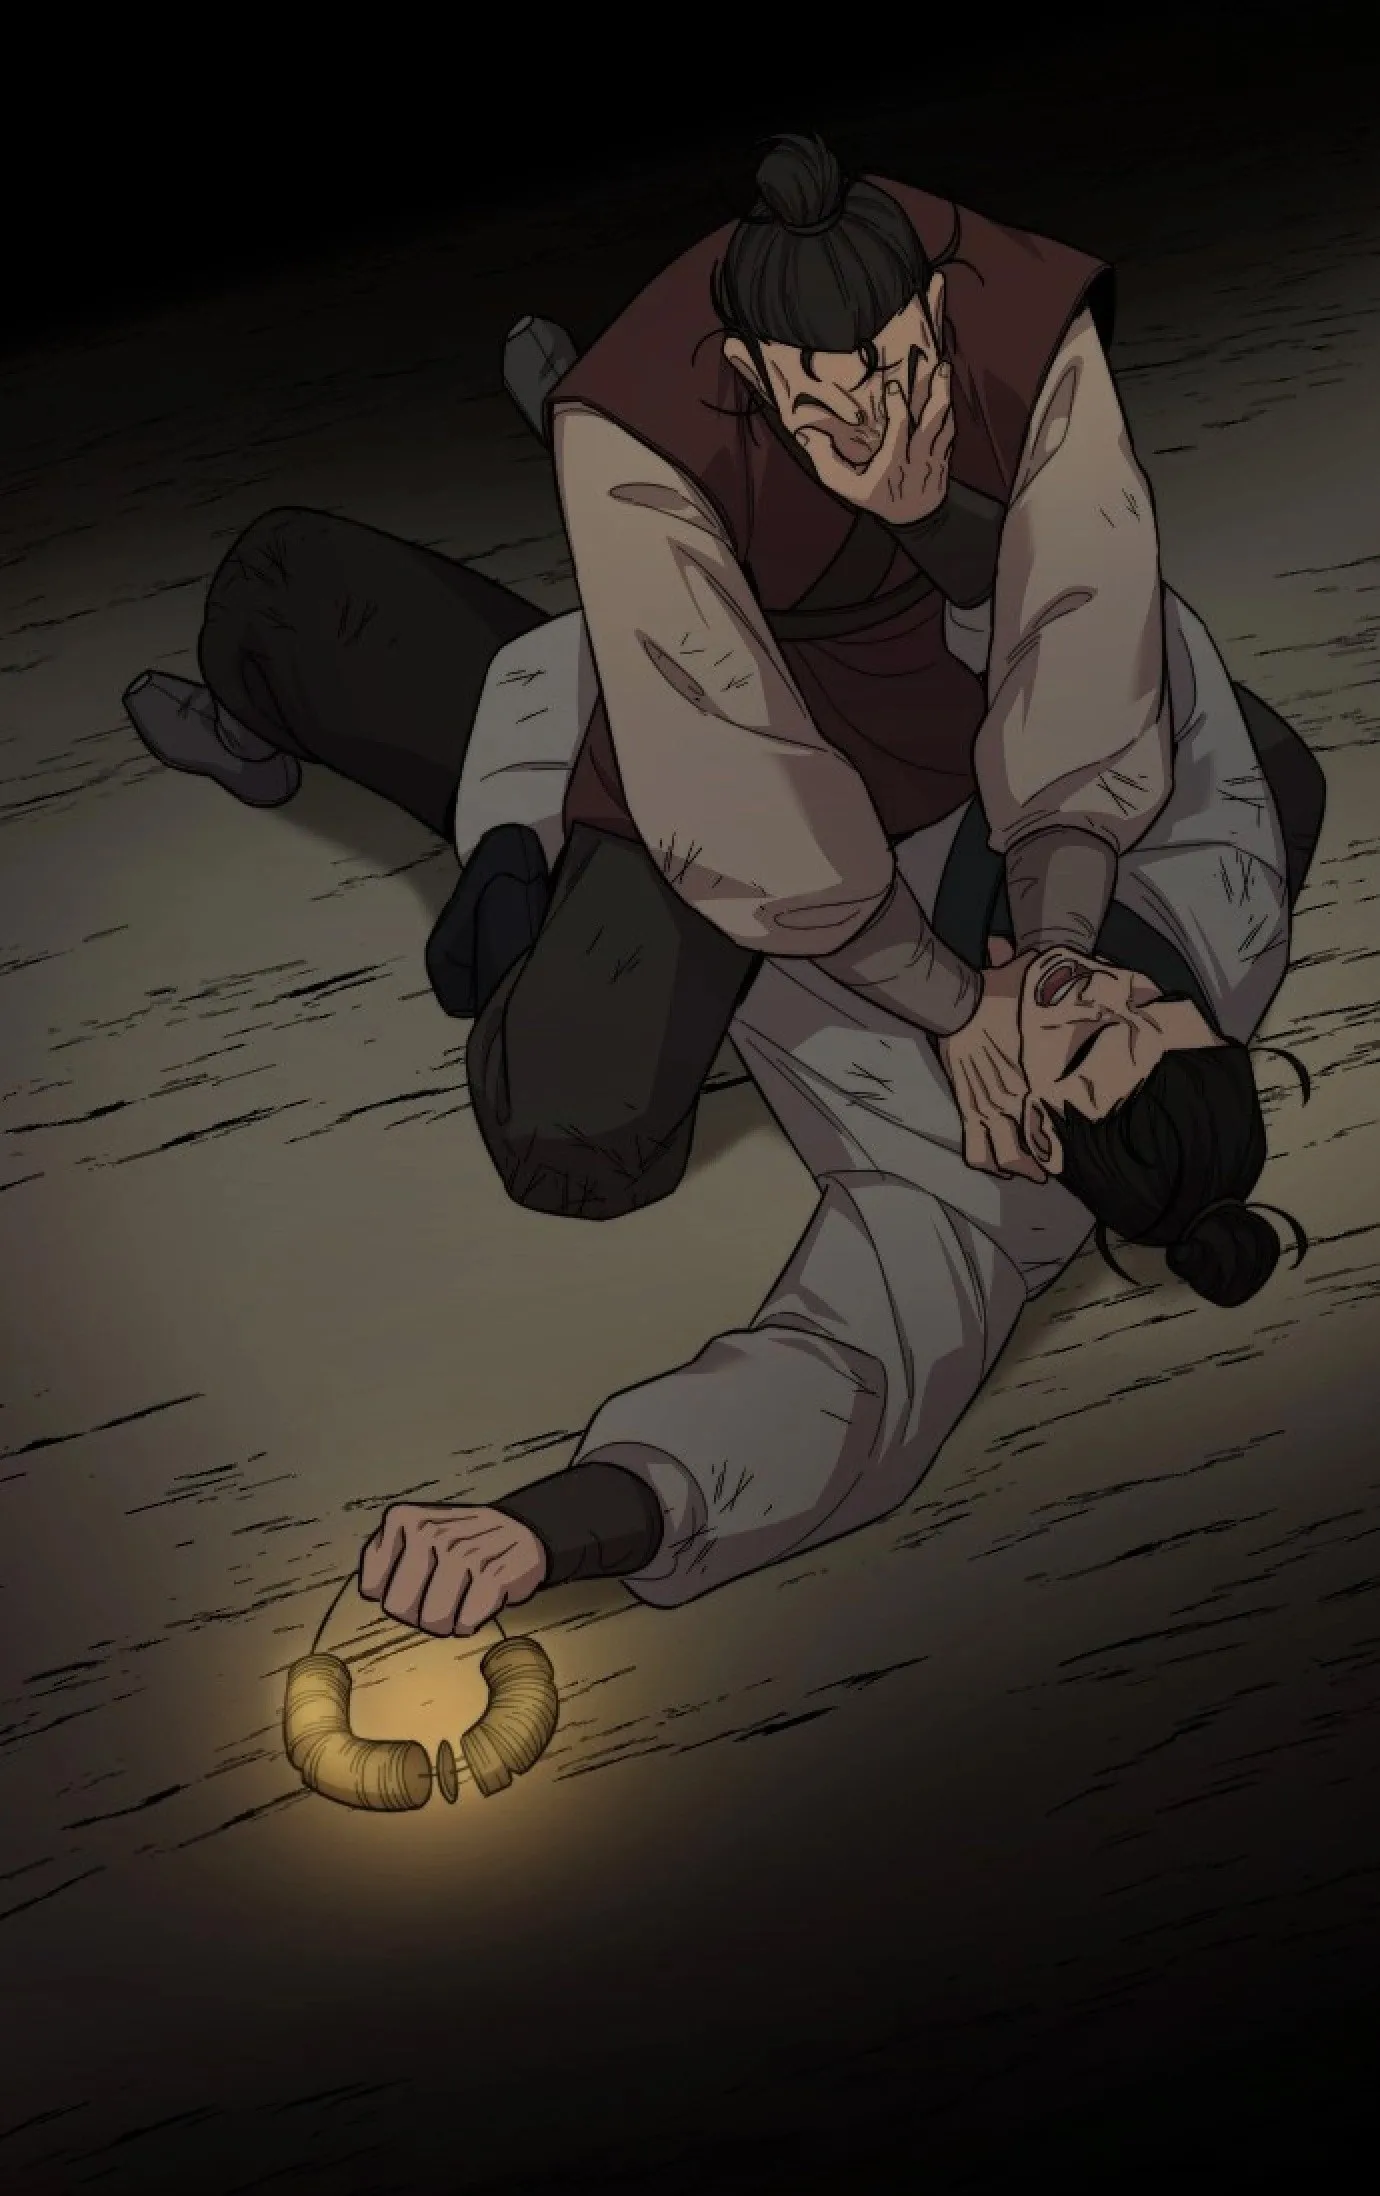
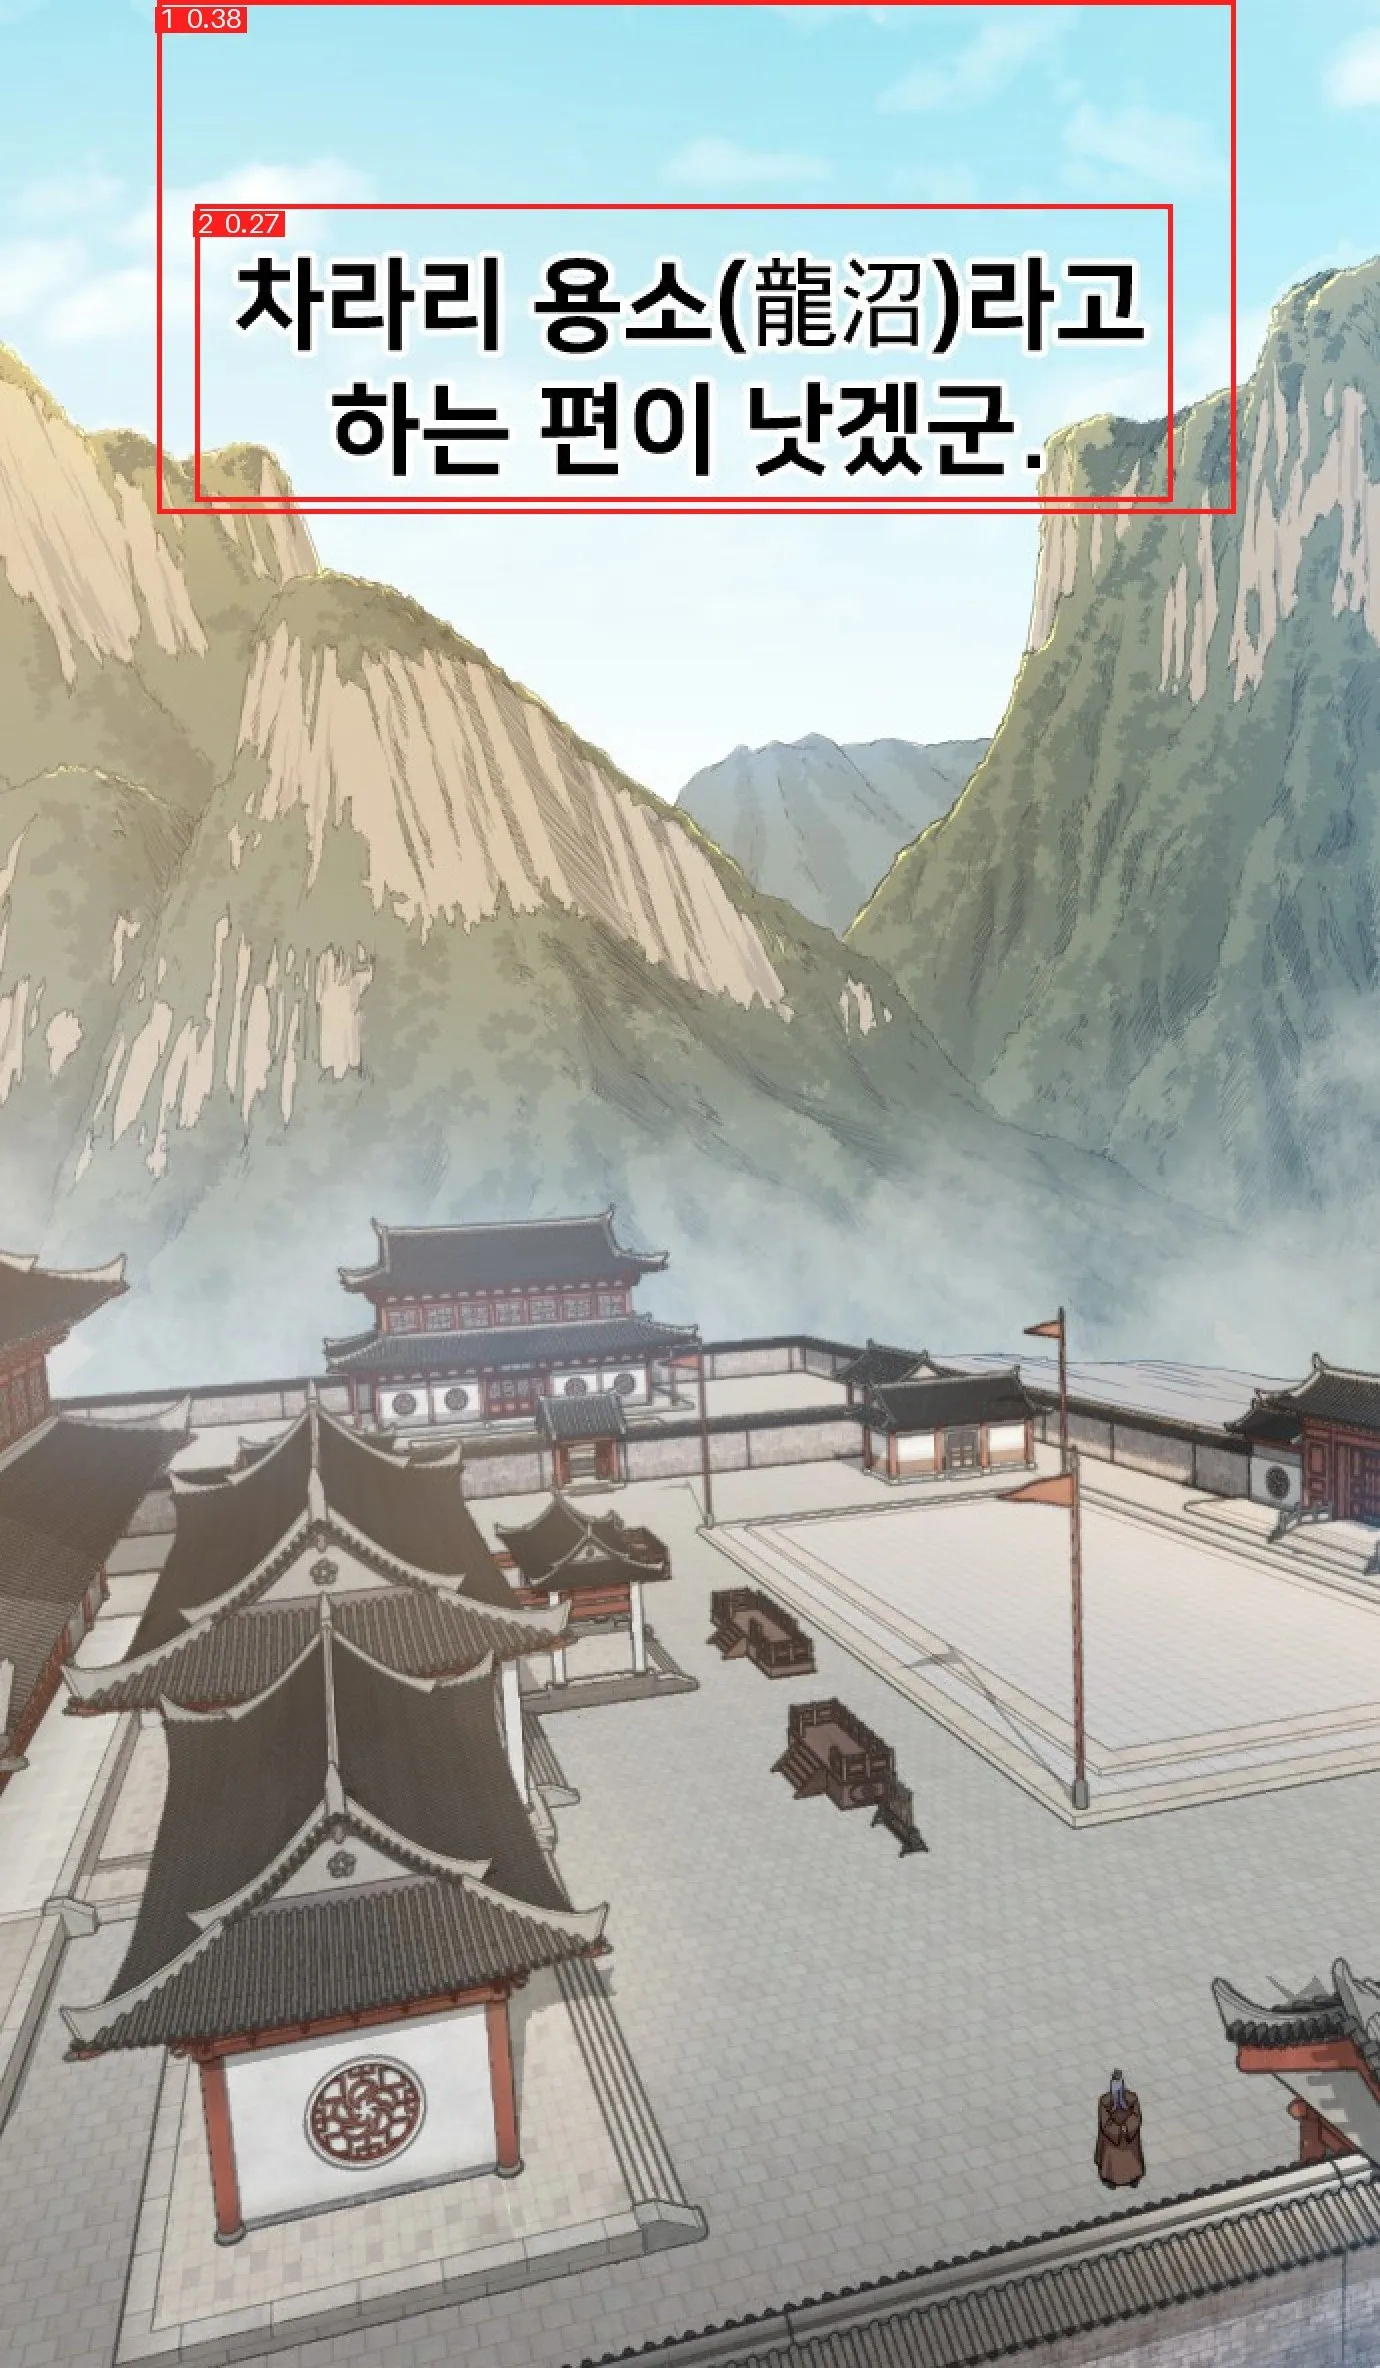
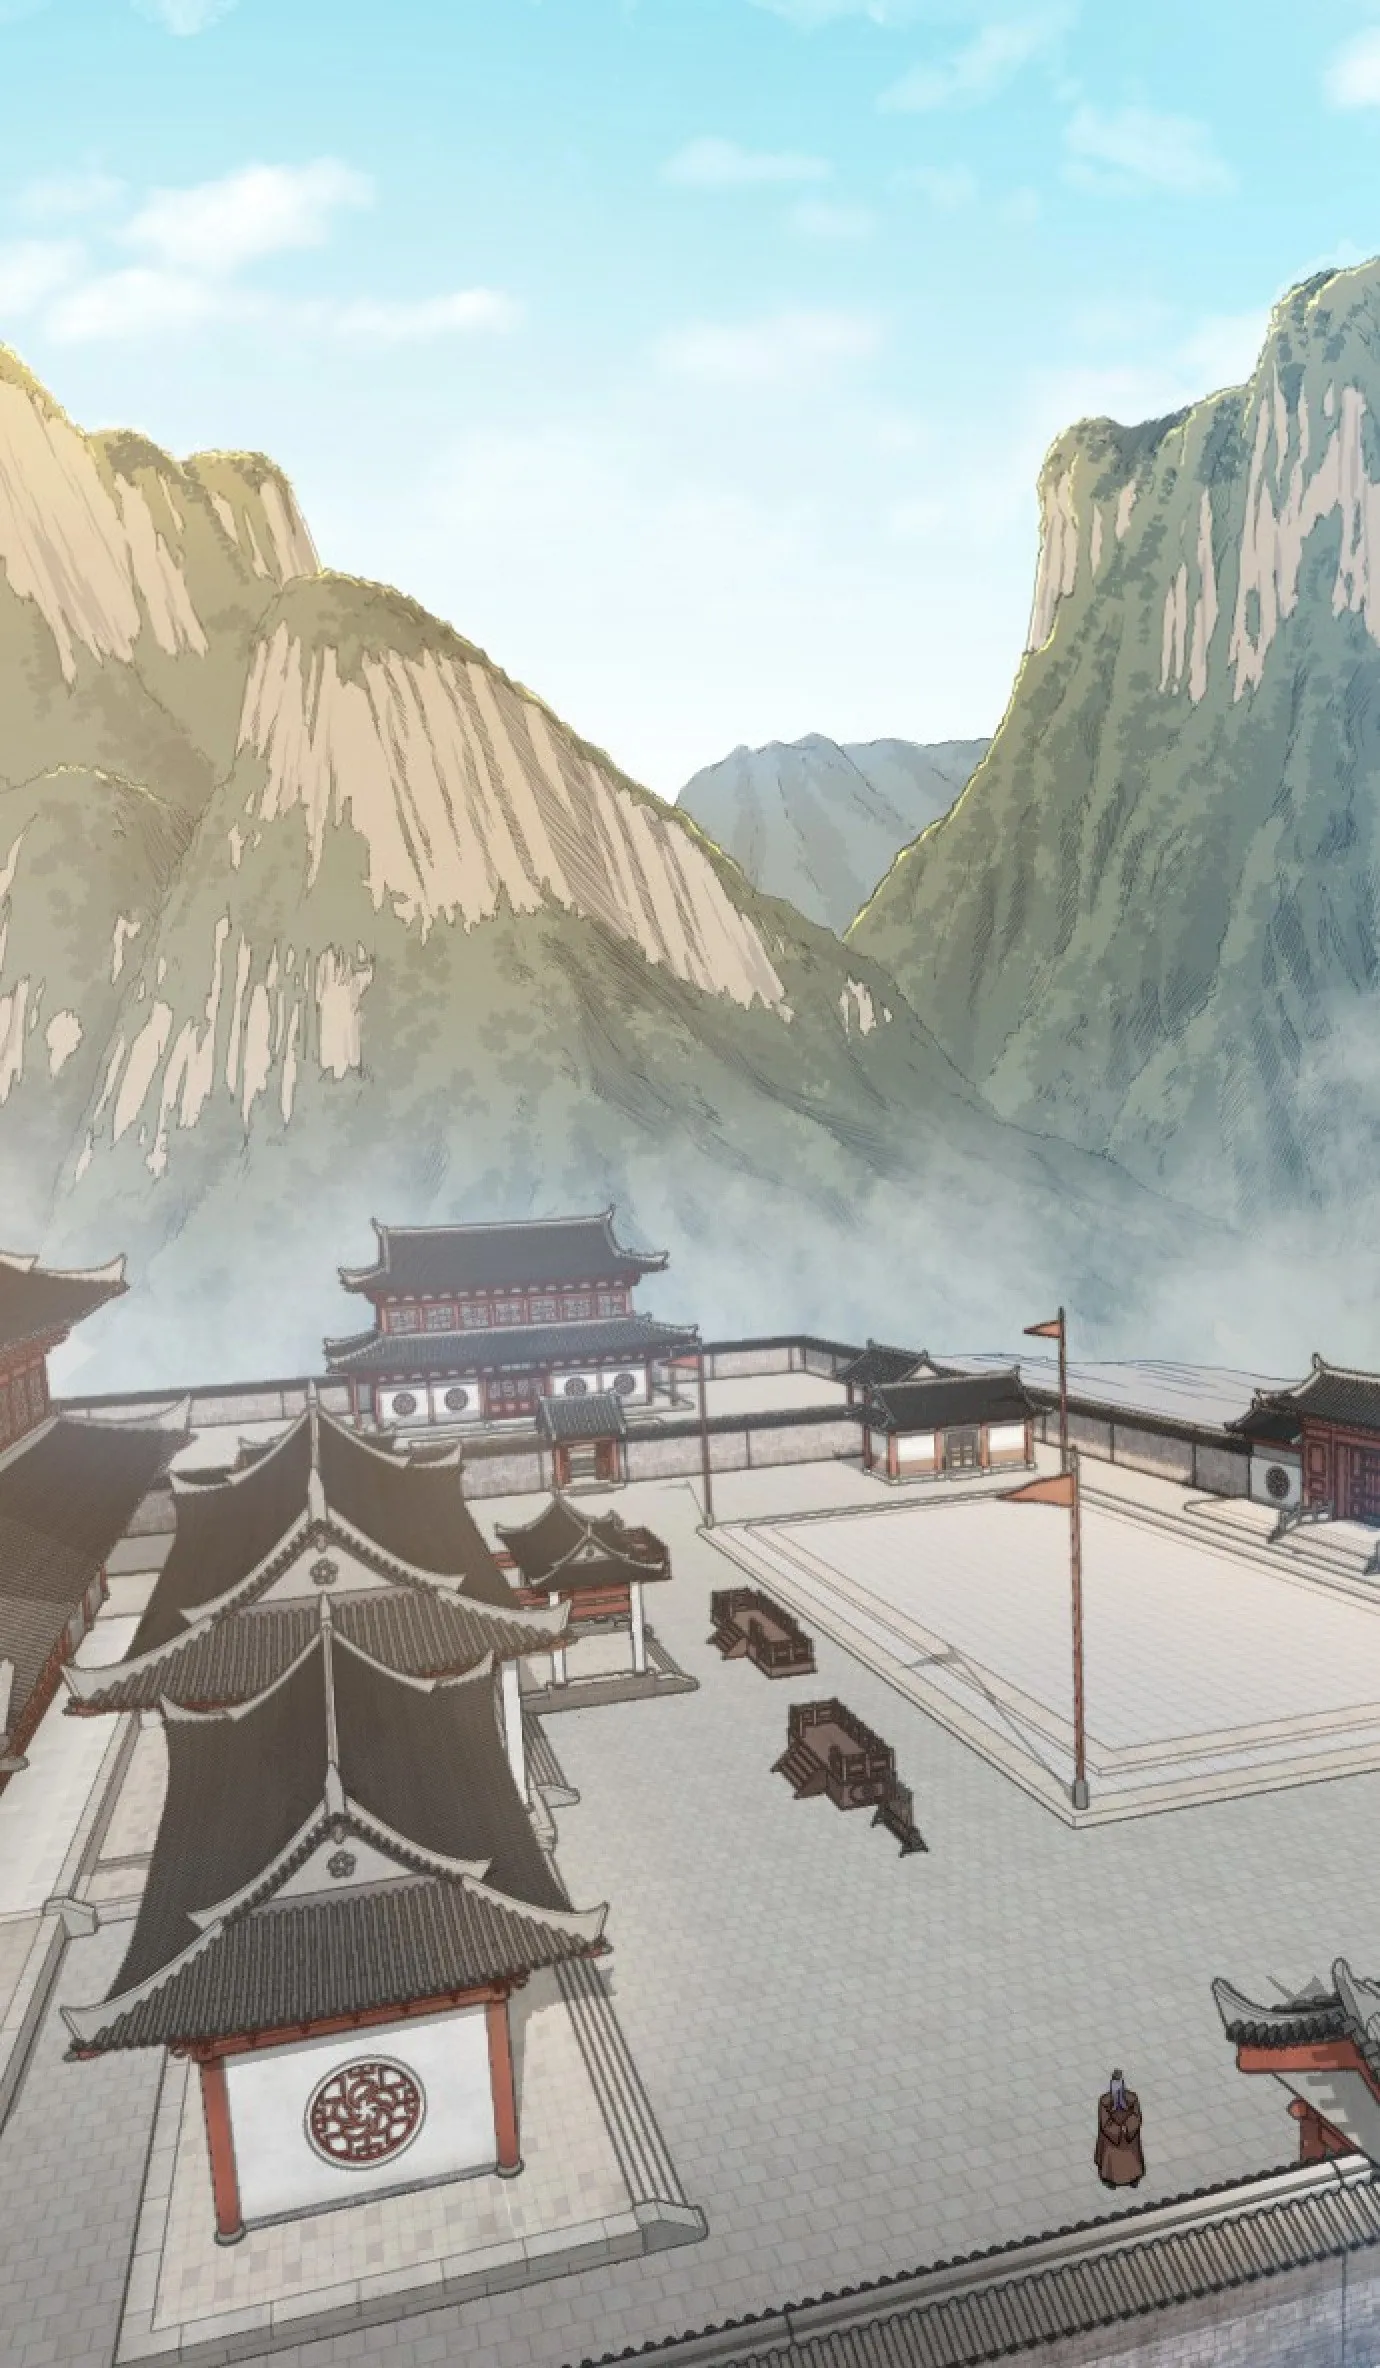
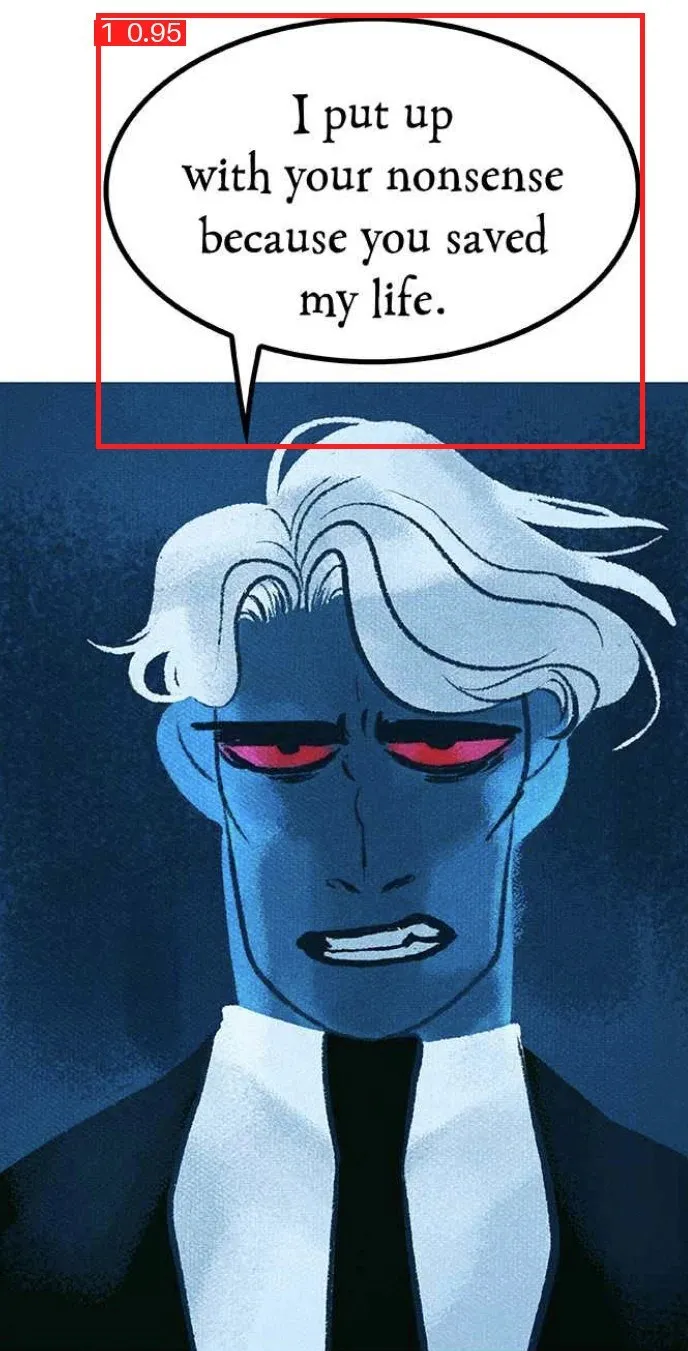
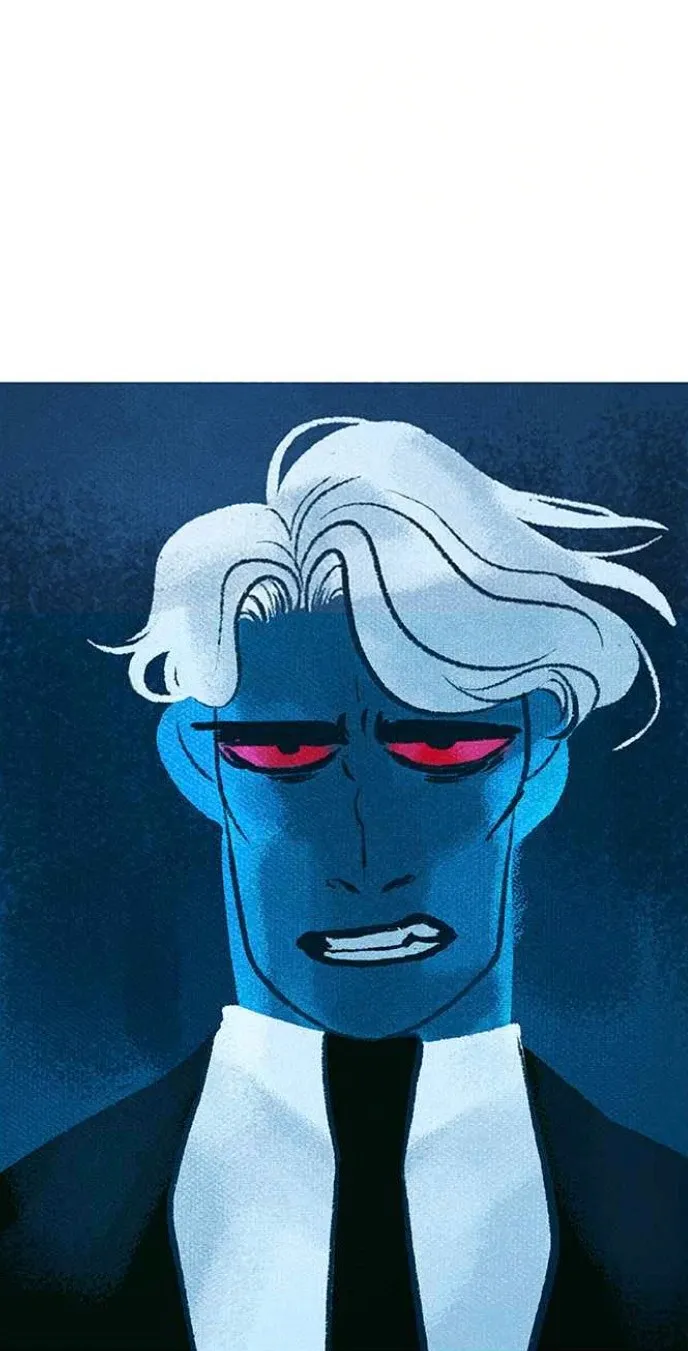
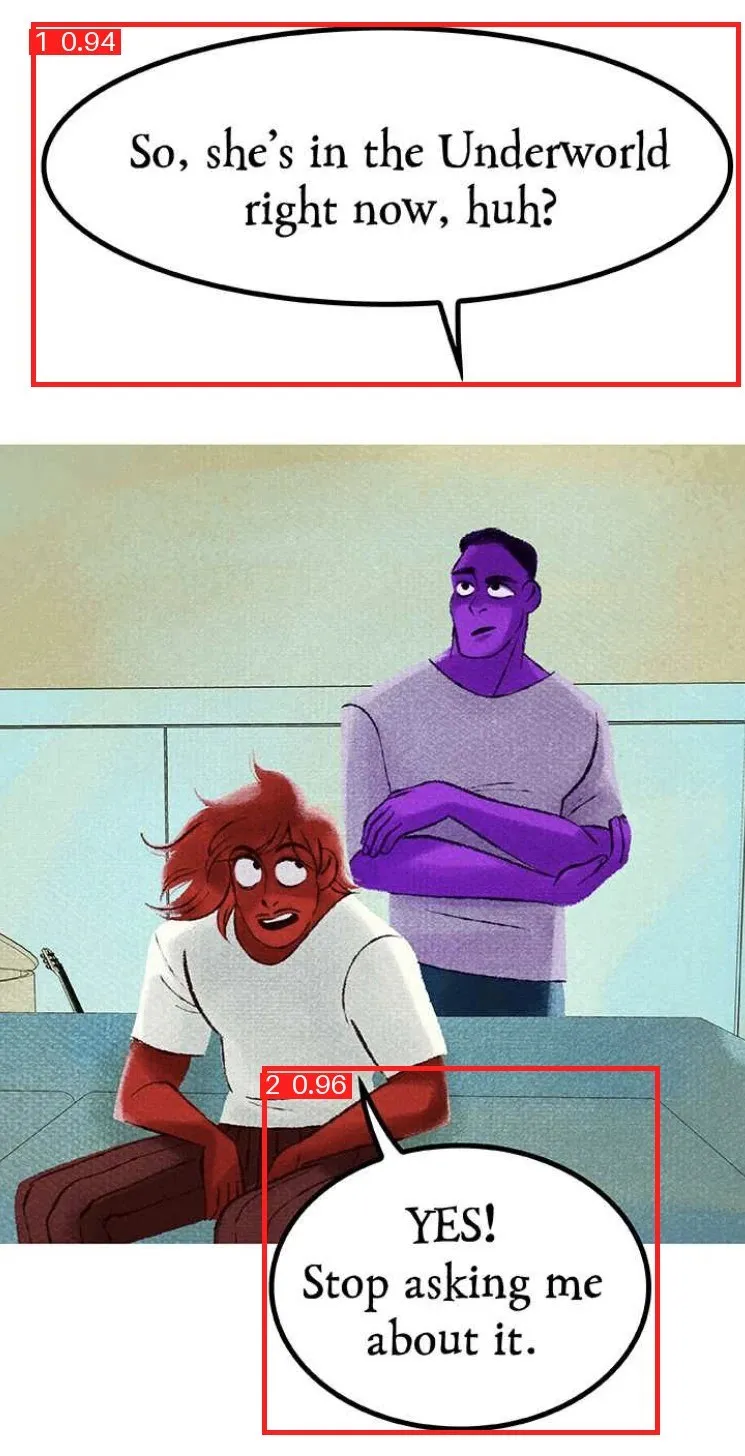
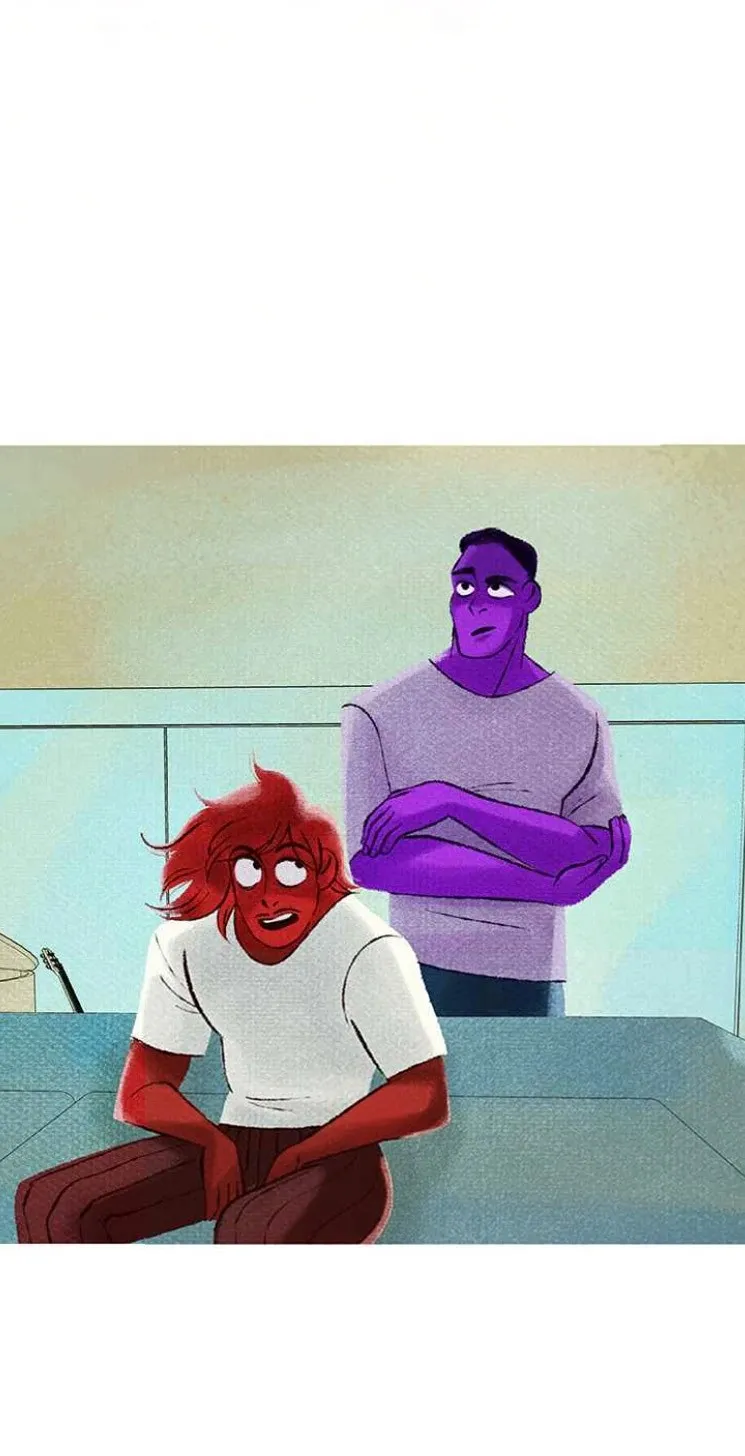
I also ran the same model (text-v5, confidence 0.25 or higher) on vertical-scroll webtoons from three countries whose art styles differ from the training domain. The KR, US and JP groups in the gallery below are the results, showing only the panels where at least one box was found. For KR and US the left image is the detection and the right one has the text erased with NovelAI inpainting. For JP the detection is on top and the erased version below.
- KR, Return of the Mount Hua Sect: 6 boxes in 4 of 8 panels
- US, Lore Olympus: 5 boxes in 3 of 5 panels
- JP, Chitose Is in the Ramune Bottle (vertical-scroll edition): 4 boxes in 1 of 2 panels
Demo images: Return of the Mount Hua Sect Fandom wiki, Lore Olympus Fandom wiki, PR TIMES press release (CLB TOKYO × Shogakukan). All rights belong to the respective rights holders. I drew detection boxes and confidence scores on top of the originals to demonstrate performance.
The charts below show the training log and the unseen-work scores.
trainval
epoch 151val 0.353train 0.310
epoch
Validation loss keeps falling with training loss until epoch 190, so there is no sign of overfitting. The sharp drop in training loss over the last 10 epochs is where mosaic augmentation is switched off.
Show as table
| epoch | train | val |
|---|---|---|
| 1 | 1.123 | 1.048 |
| 50 | 0.670 | 0.623 |
| 100 | 0.533 | 0.411 |
| 151 | 0.464 | 0.366 |
| 200 | 0.310 | 0.353 |
Scored on 1,005 approved cuts from 34 works that none of these three models trained on.
Show as table
| model | mAP50-95 |
|---|---|
| text-v2 · trained on 1 work | 0.616 |
| text-v3 · trained on 2 works | 0.796 |
| text-v4-2 · trained on 2 works | 0.844 |
gallery (16)
KR · Return of the Mount Hua Sect (images from its Fandom wiki) · left: detection, right: NovelAI inpainting
US · Lore Olympus (images from its Fandom wiki) · left: detection, right: NovelAI inpainting
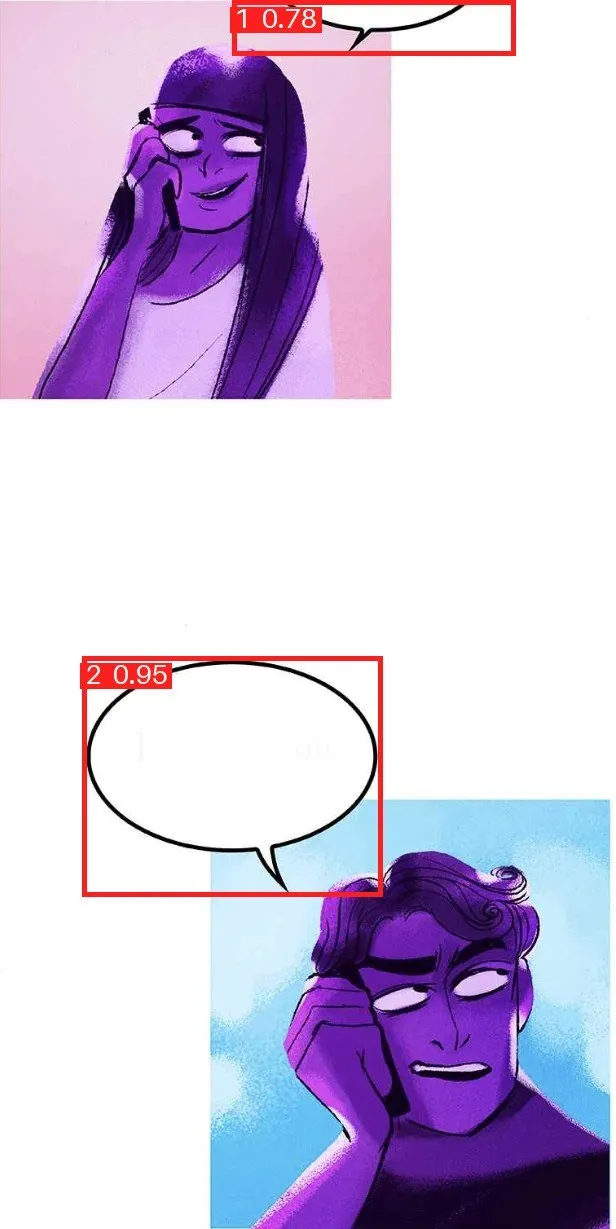
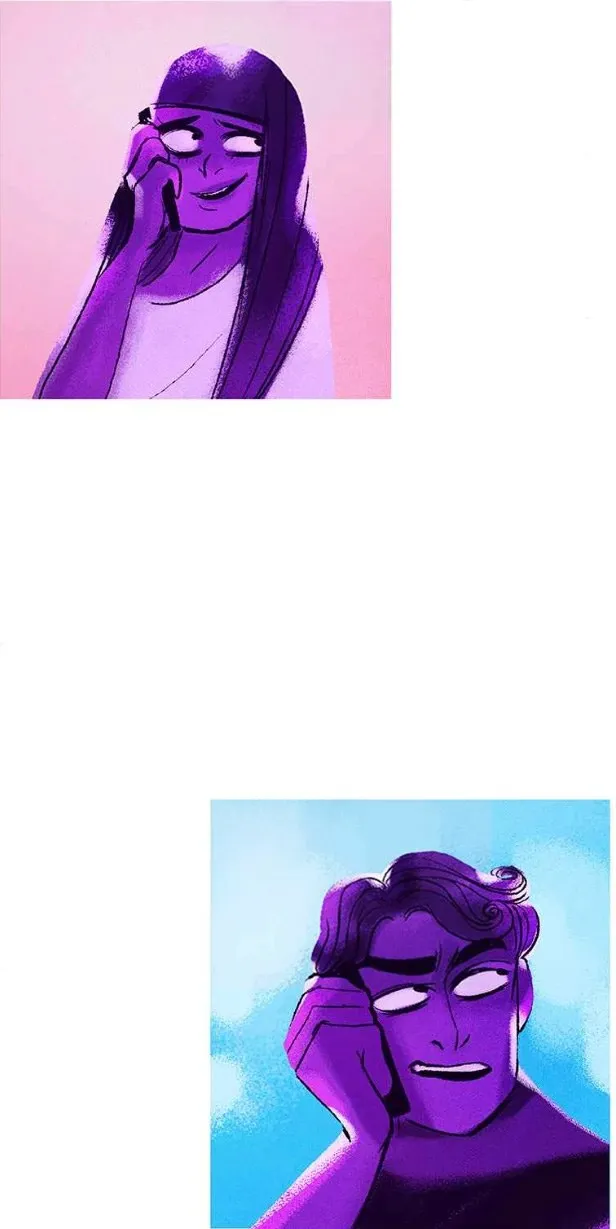
JP · Chitose Is in the Ramune Bottle, vertical-scroll edition (PR TIMES press image) · top: detection, bottom: NovelAI inpainting